Mastering Kubernetes Commands: kubectl, Troubleshooting, and Production Operations
Six reads before you delete a crash-looping pod: context, namespace, get, describe, logs, and events. kubectl client v1.36.1 on 11 October 2026.
Tagged

Six reads before you delete a crash-looping pod: context, namespace, get, describe, logs, and events. kubectl client v1.36.1 on 11 October 2026.

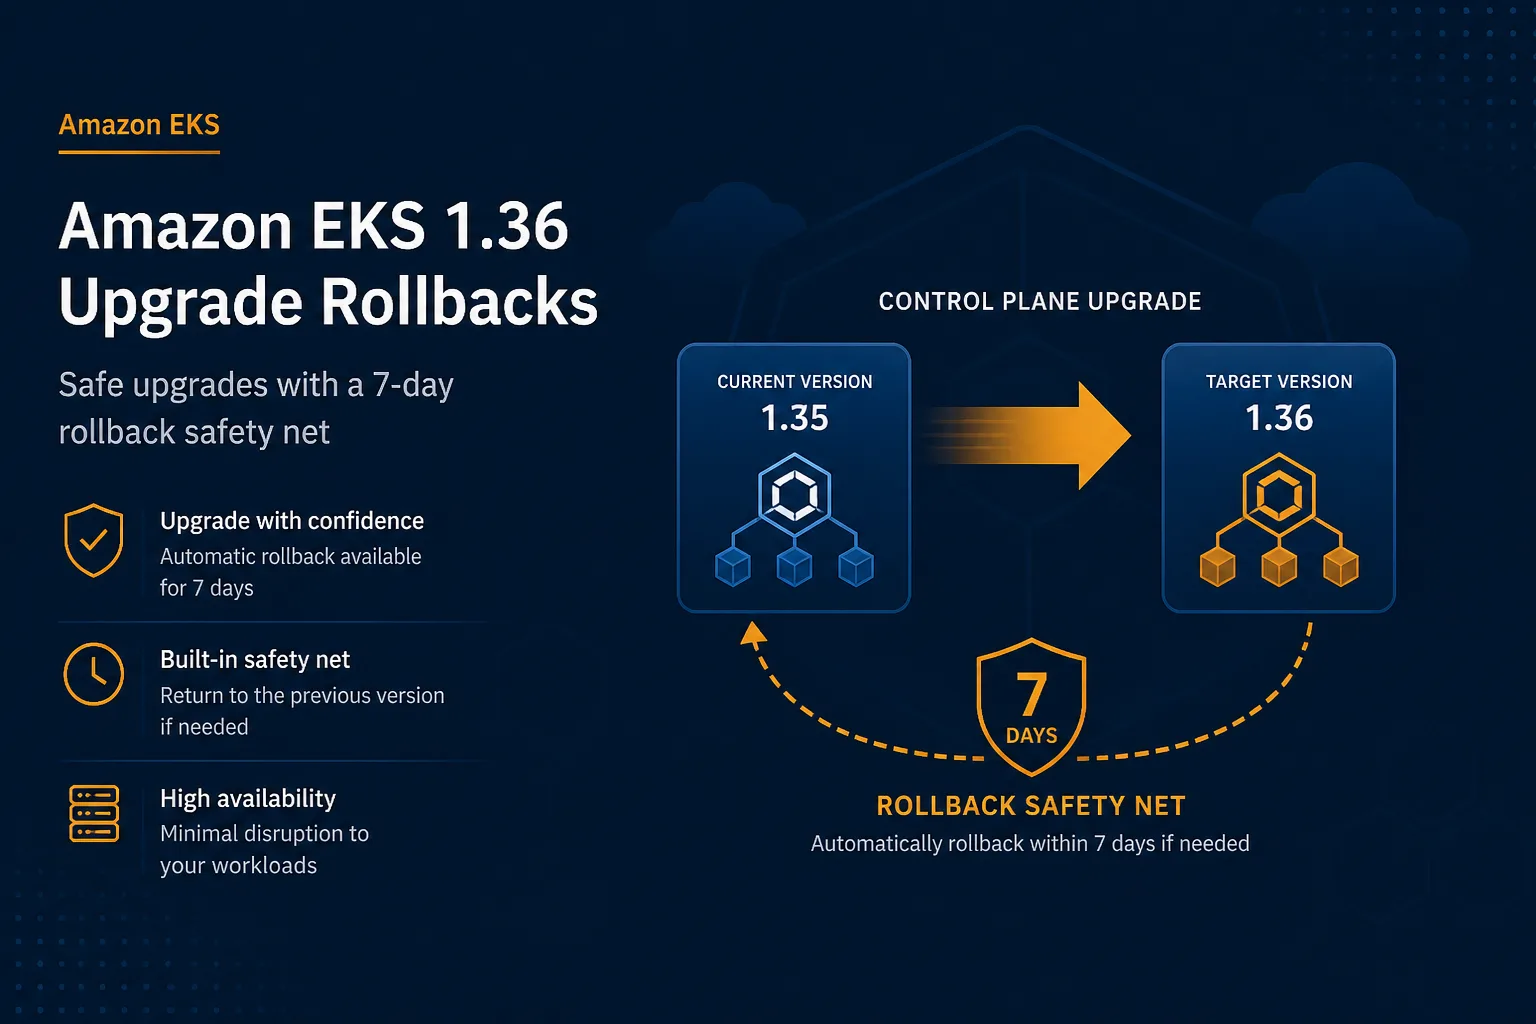
EKS Kubernetes 1.36 is available with user namespaces GA and mutating admission policies. Since July 2026 you can roll back an in-place control-plane upgrade within 7 days at no extra charge — but only N→N-1, and Fargate or strict PDBs can block you.

For a product SaaS (~12 production nodes, 3 clusters), EKS Auto Mode cut internal K8s ops from 80 to 35 hours/month at similar compute spend — partner MSP quote was $6,500/mo on top for 24/7 paging alone.

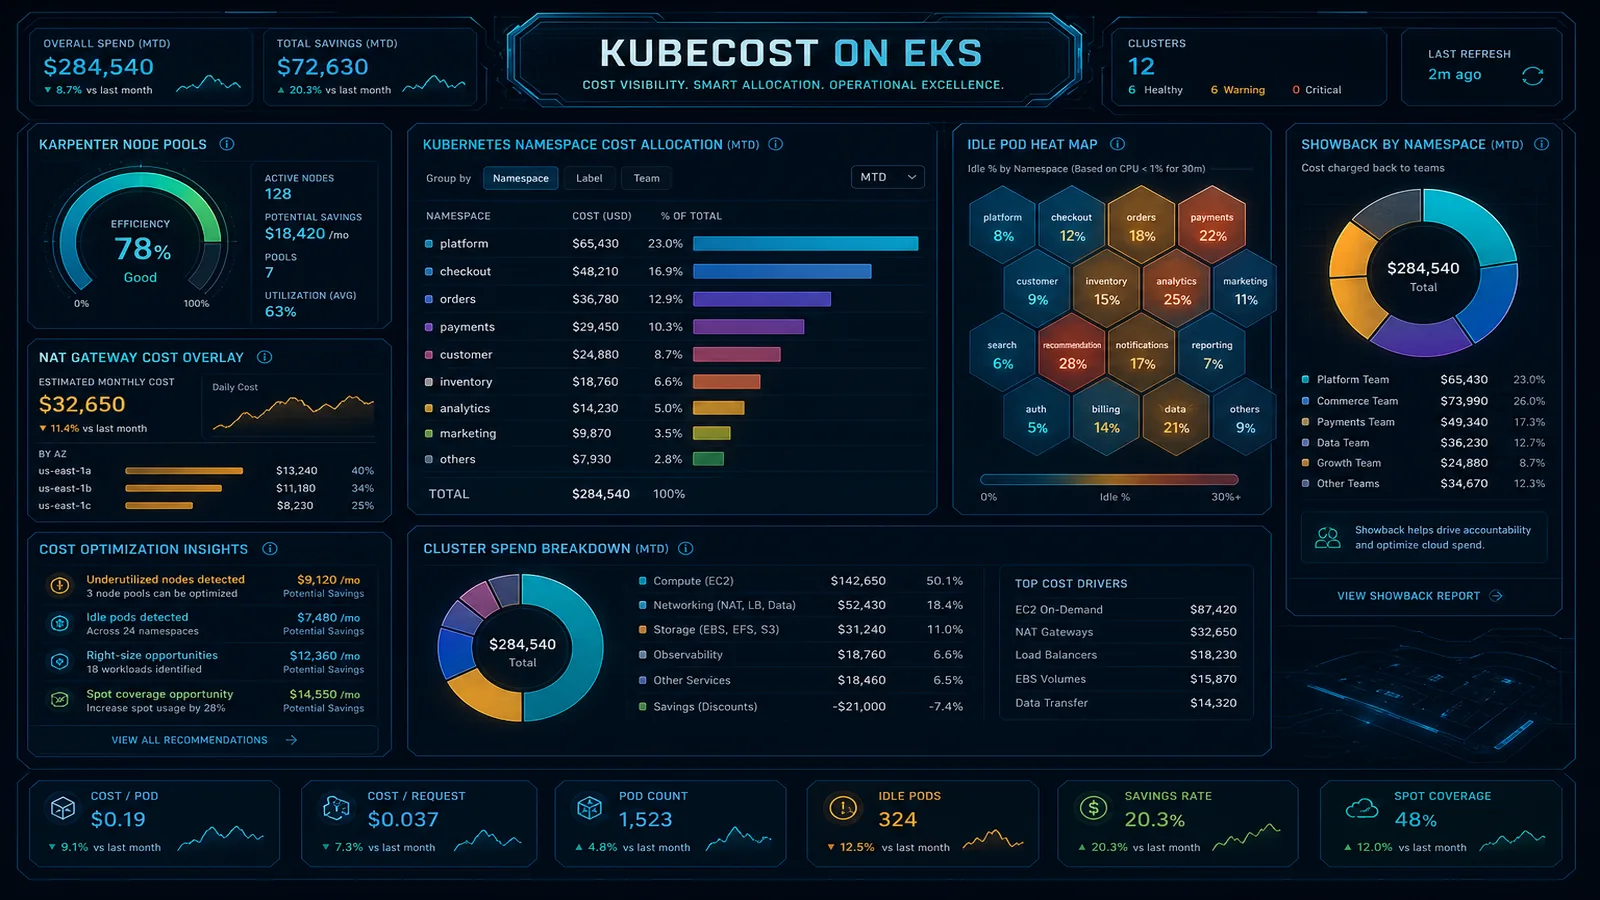
Production guide for Kubecost on AWS EKS — cost allocation setup plus architecture changes that reduce spend, not just attribute it.

EKS control planes are $73/month per cluster. Stay on a Kubernetes version beyond its 14-month standard support and Extended Support bills $0.60/cluster-hour — $438/month per cluster, a 6× multiplier vs standard. EKS Auto Mode adds a ~12% markup over standard EC2 + EBS for managed compute simplicity. The compute side (Karpenter, Spot, Graviton) is where most of the bill lives.

Default Docker seccomp is not enough for regulated workloads. EKS Pod Security Standards, seccomp profiles, and Fargate platform version constraints.

Cluster upgrades and Karpenter consolidation look healthy in the console while PDB-blocked evictions freeze your node drain for 45 minutes. This guide wires minAvailable, maxUnavailable, and EKS managed node group semantics.

App Mesh is legacy path—new meshes should start with VPC Lattice for AWS-native east-west or Istio on EKS when you need full L7 policy. Traffic shifting without duplicating load balancers per service.

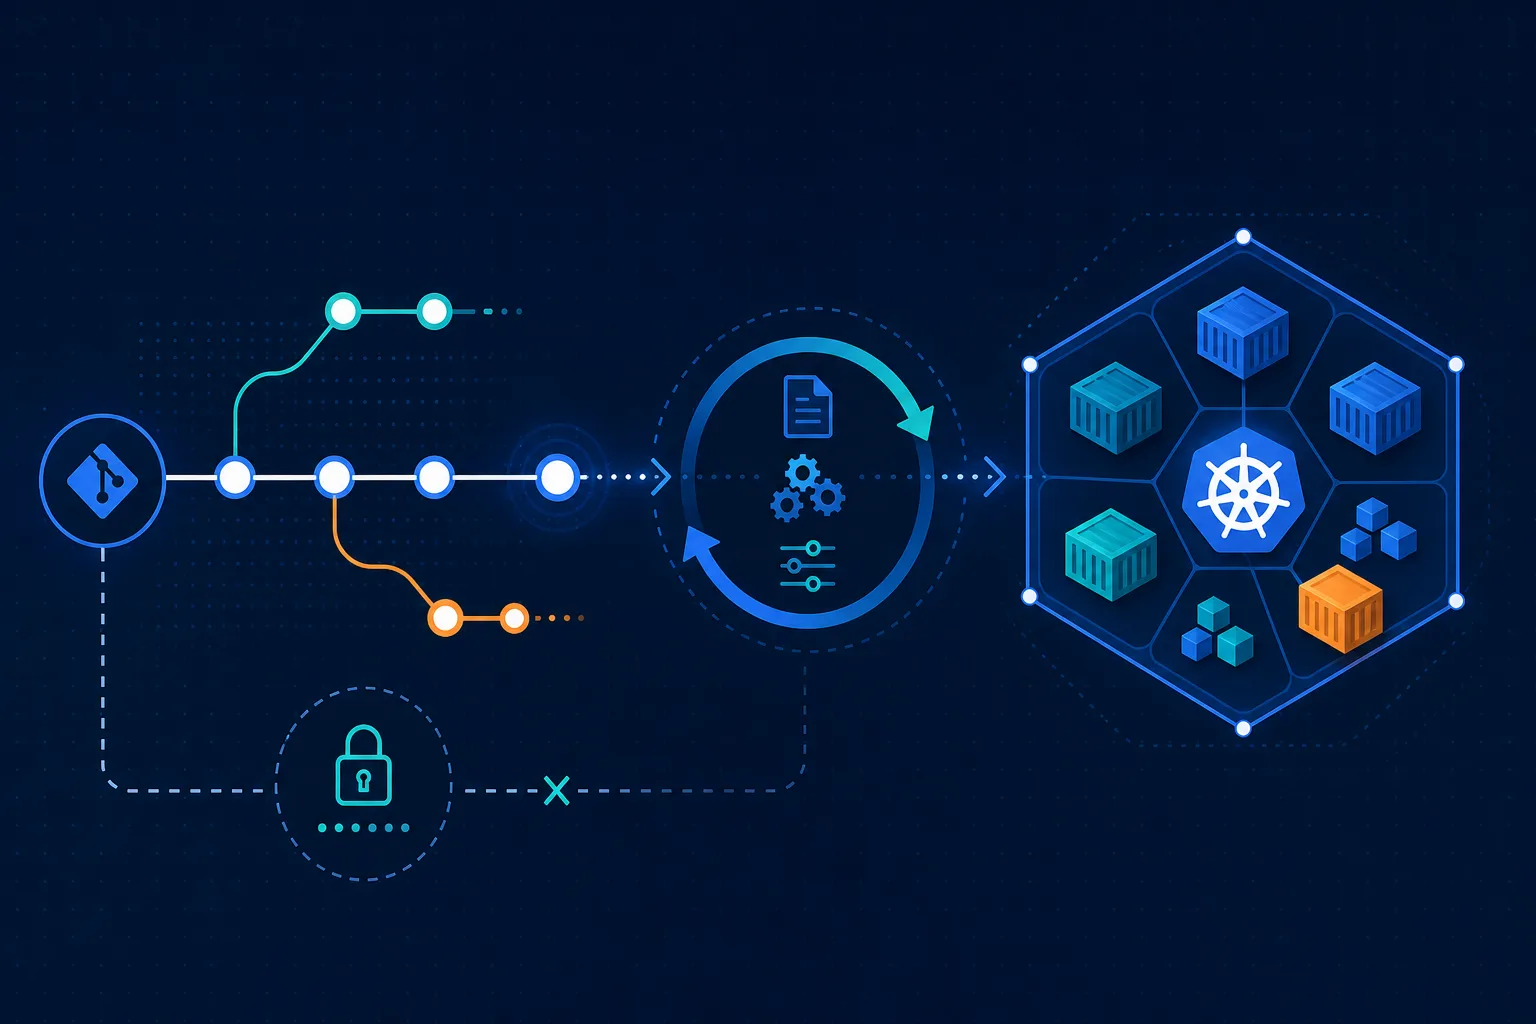
AWS Prescriptive Guidance says Argo CD and Flux both handle most GitOps scenarios capably — so picking one is a fit decision, not a winner. The decisions that actually cause incidents are the ones underneath: plaintext secrets in the GitOps repo, CI running kubectl apply and reintroducing drift, no App-of-Apps so onboarding is click-ops, and repo topology you can't change later. Here is the Argo CD vs Flux matrix, an App-of-Apps example, and the five traps independent of tool.

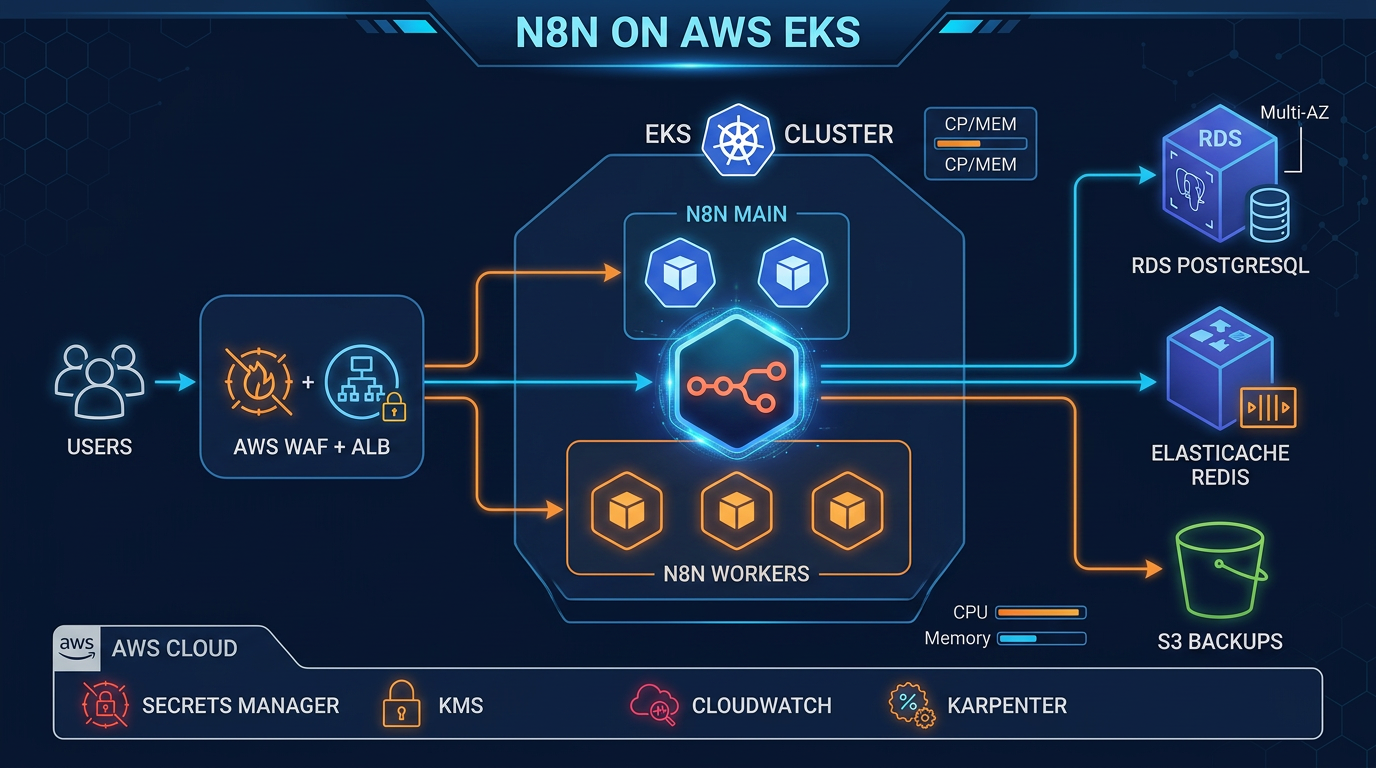
n8n on EKS: queue mode, RDS Postgres, Redis/Valkey, ALB+WAF, IRSA. July 2026 production checklist.

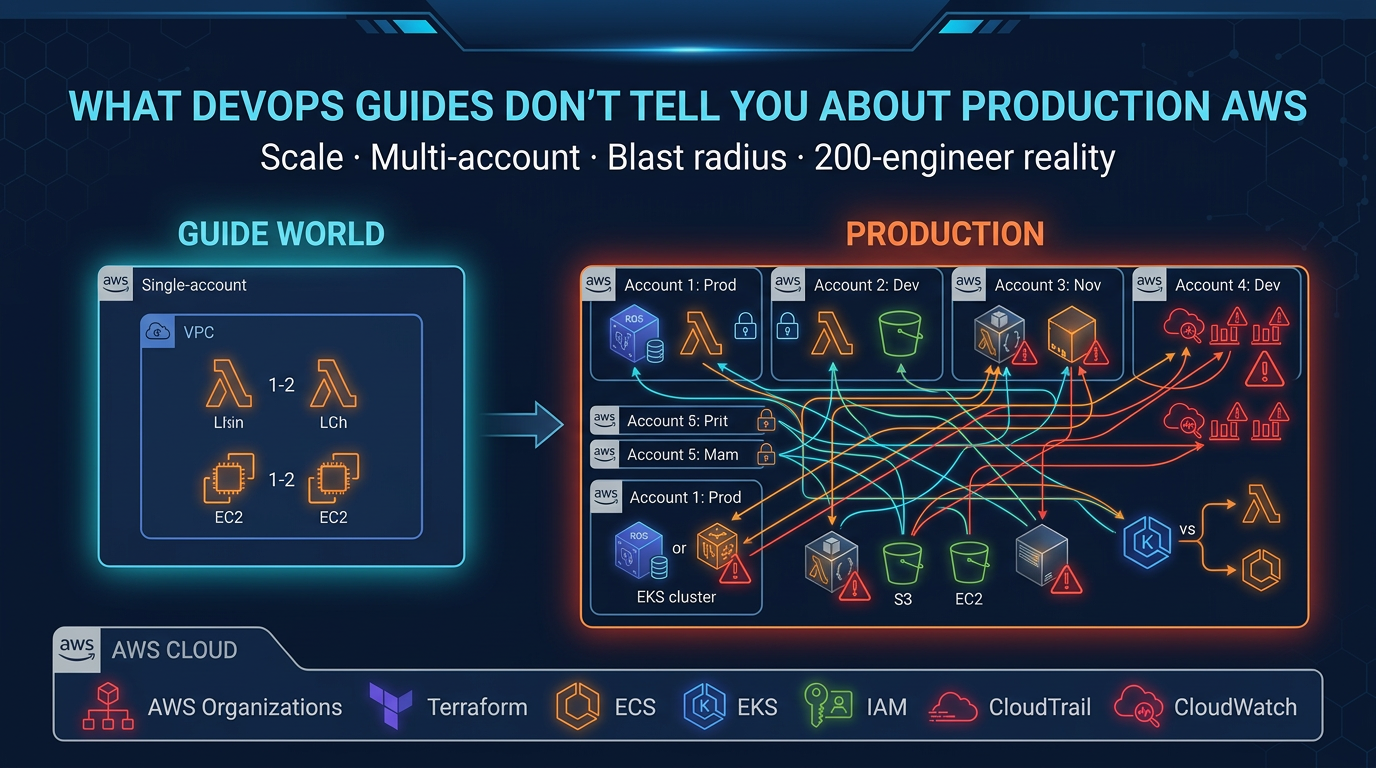
Most DevOps guides teach what AWS services are. Production teaches what happens when 200 engineers use them together. Here's the gap.

Karpenter replaces Kubernetes Cluster Autoscaler with intelligent bin-packing and just-in-time node provisioning. This guide covers setup, consolidation, cost optimization, and production patterns for EKS clusters.